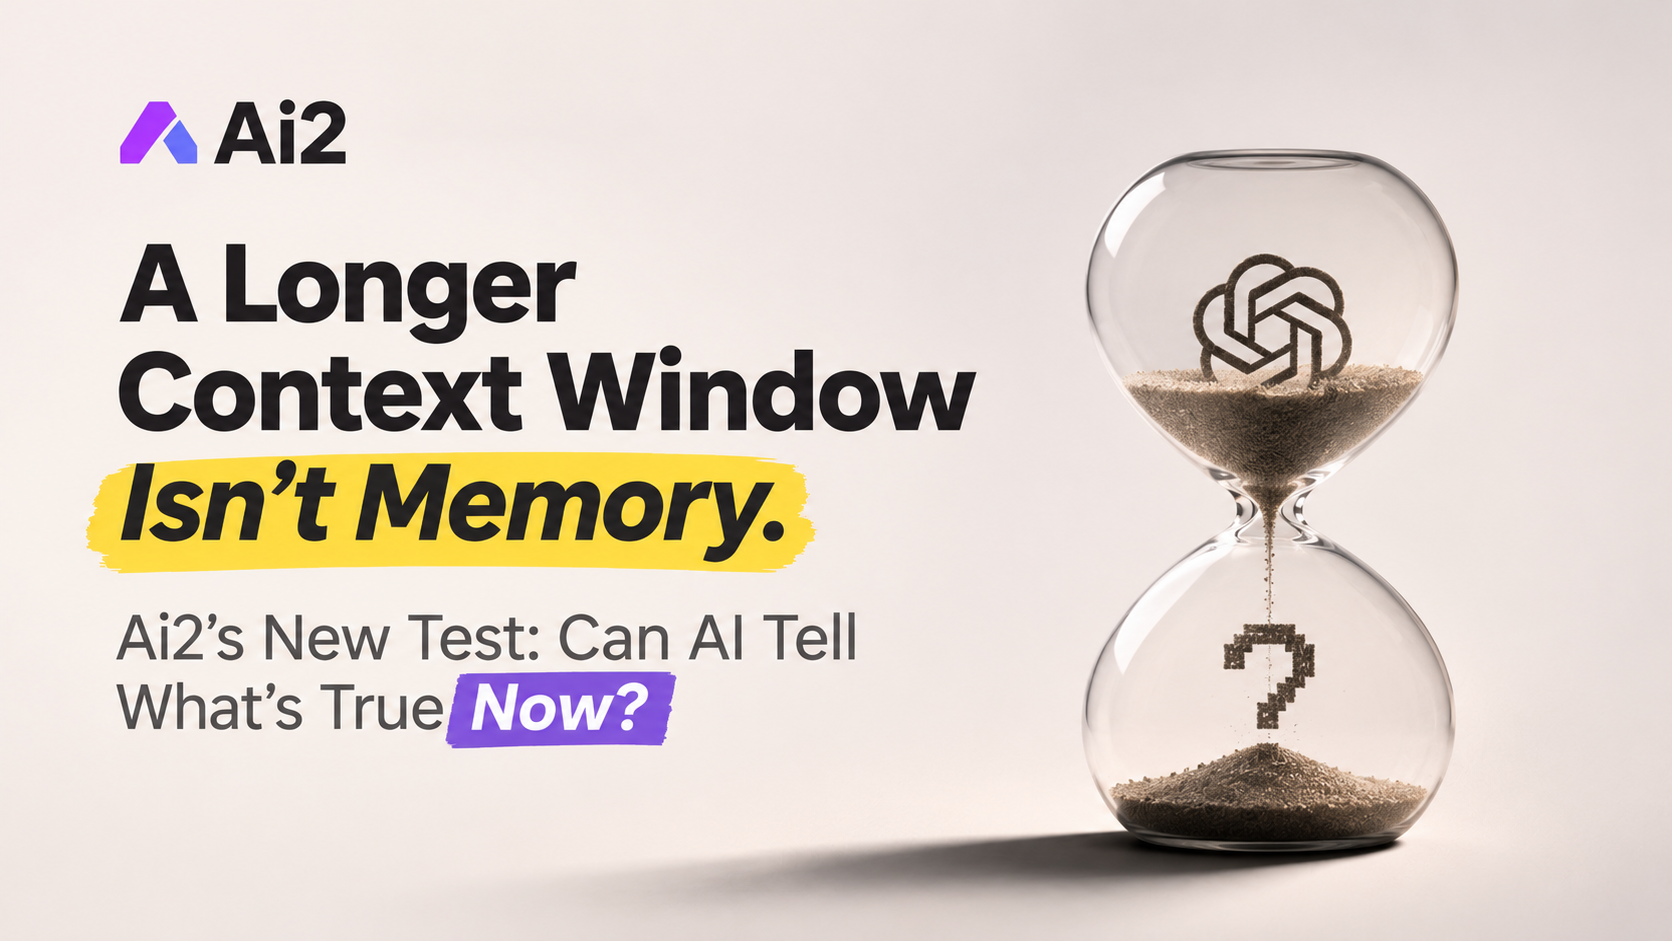

Fitting a document into an AI model's context window is not the same as the model keeping track of it. Ai2's new benchmark, StateBench, tests that gap directly. It asks whether a language model can follow information that changes over the course of a document, such as a fact about an entity that is later replaced or updated. On the benchmark's longest "general-finite" tasks, the models Ai2 tested scored 13% accuracy or less, according to Ai2's announcement on Hugging Face. Ai2 reports that the frontier models it evaluated declined sharply as the tasks got harder and the documents got longer.
The test is about the latest state of a fact, not about finding it. A model can pull out an early detail, summarize a passage, or write a fluent answer and still get the current state wrong. StateBench checks whether the model applies a sequence of stated changes and returns the resulting state. The paper describes a four-tier hierarchy for long-horizon state tracking. Its authors call the problems "soluble": the document holds everything needed to derive the answer, and no outside knowledge is required. The abstract says pretrained models do not robustly solve them.
For anyone using AI on long records, the point is that a bigger window tells you how much text a model can take in, not whether it keeps the consequences of changes within that text. When a record has revisions, cancellations, replacements, or exceptions, an answer built on an earlier fact can read as coherent and still be wrong. That can be worse than an answer that says "I don't know." The public materials give no error rates for real uses such as legal review, inventory, incident response, or policy analysis. Those setups may add retrieval, databases, tools, or human checks that StateBench doesn't represent.
The result has limits. The 13% figure applies to the longest, hardest cases, not to every long-context prompt. It doesn't show that models can't track state at all, and it doesn't test every method for improving reliability. The public descriptions also don't say which models were tested, how each one scored, or what prompting setups were used. If your system depends on the latest version of a fact, test that requirement directly instead of inferring it from a context-window spec.