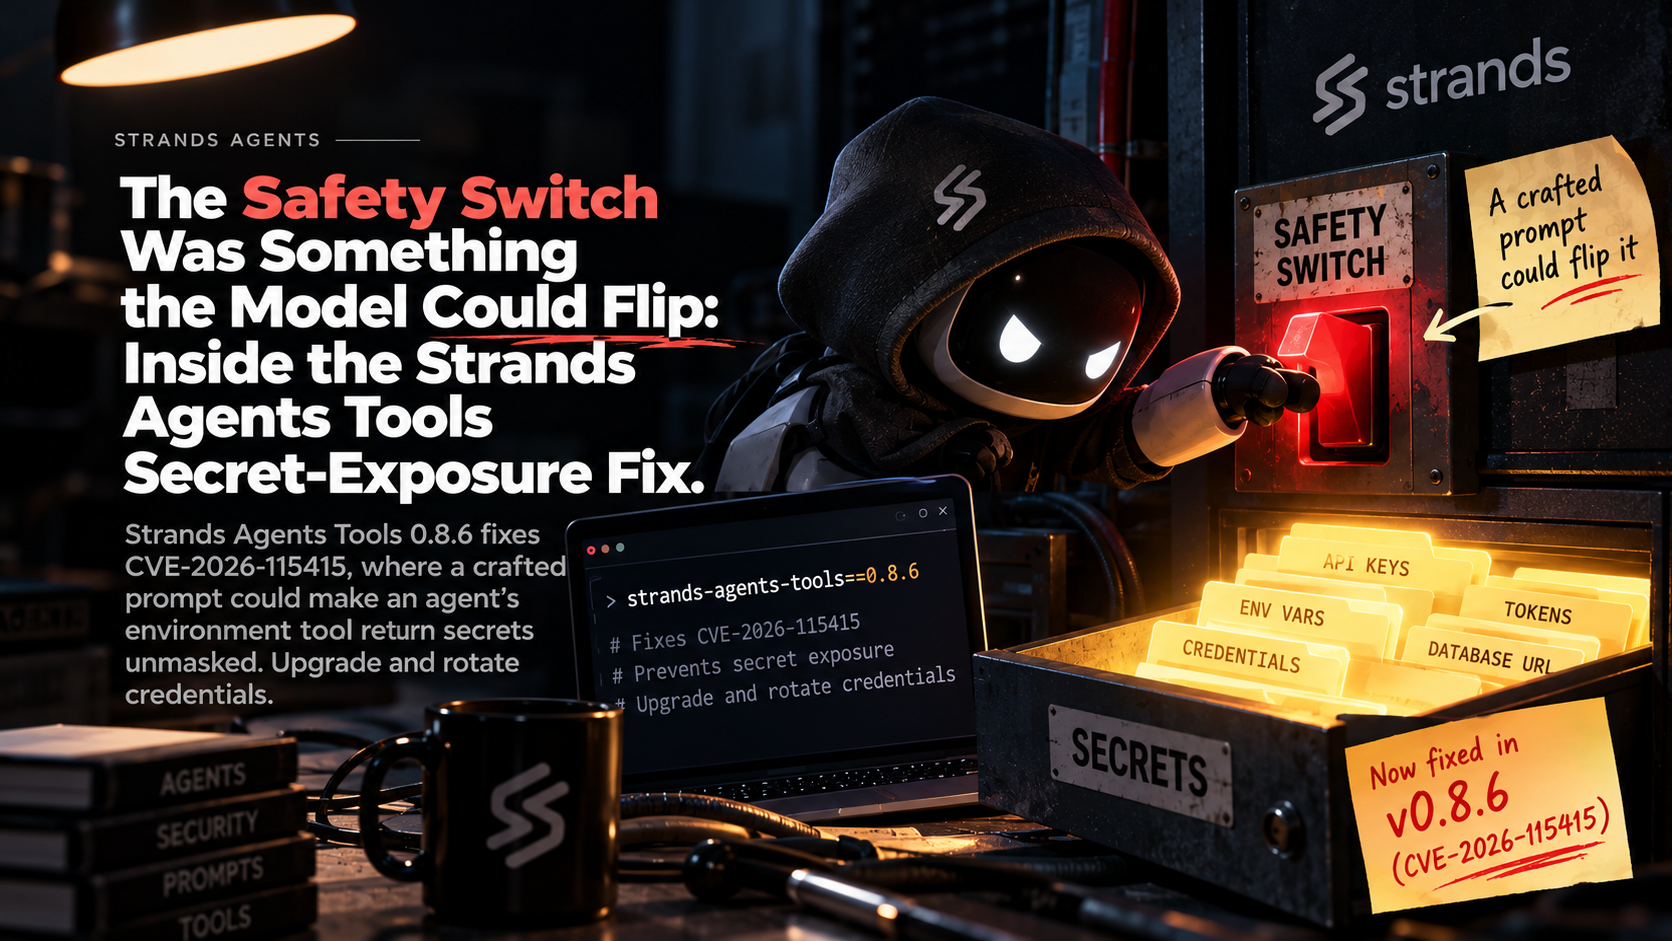

Strands Agents Tools version 0.8.6 fixes a flaw that let prompt-injected content make an AI model turn off secret masking and return a host’s environment variables in clear text. Those variables can include cloud credentials and API keys. The fix is to upgrade to 0.8.6 or later and rotate any credentials that were present in the environment of agents that loaded the environment tool.
What went wrong, in plain language. Agent tools often need to read settings from the machine they run on, such as passwords and API keys stored as environment variables. The tool is meant to hide those values by default. According to the advisory, the control that decided whether to hide them was exposed as something the model itself could set when calling the tool. That meant untrusted text the agent read, such as a web page or document, could steer the model into asking for the secrets unmasked, with no operator choosing to reveal them. The problem wasn’t only that an agent could read environment data. The safeguard was something the model could switch off.
The scope. The CVE record, CVE-2026-115415, lists affected versions from 0.1.0 up to, but not including, 0.8.6. It was published on October 28 and rated medium severity, with a score of 5.9 under CVSS 4.0. Another source scores it 6.5 under the older CVSS 3.1 system. A medium score reflects that an attacker has to get the crafted content in front of the agent. If an agent that read such content also had valuable credentials available, the impact is still high.
What to do now.
Upgrade strands-agents-tools to 0.8.6 or later.
Identify which agents loaded the environment tool, and which sensitive variables those agents could access.
Rotate the credentials in those environments, even without signs of misuse.
Going forward, give agents only the variables they need.
The current source code, as described in your supplied material, now controls masking through a default setting (ENV_VARS_MASKED_DEFAULT), and the tool’s schema no longer includes an input for disabling it. That moves the decision out of the model’s tool call.
It isn’t the first of its kind. AWS has published several Strands Agents Tools bulletins this year with a similar shape: a security-sensitive setting exposed as a parameter the model could control. In July, a memory tool exposed connection settings the model could set, allowing an operator’s API key to be sent to a host the model chose (fixed in 0.7.0). Later that month, an HTTP tool exposed a proxy setting the model could control, which could leak credentials even with a host allowlist (fixed in 0.8.2). In August, memory tools exposed a tenant namespace the model could set, which could let one user’s request reach another tenant’s data (fixed in 0.8.3). AWS says the AI agent tool surface was a dominant theme in its August bulletins. The shared lesson for anyone building agent tools: don’t let the model choose settings that guard security.
What isn’t known. None of the sources reports that the flaw was exploited in the wild, names affected organizations, or says which secrets were exposed. The patch closes this specific masking bypass, and the sources don’t claim it removes every prompt-injection or secret-exposure risk in an agent runtime.
Bottom line: If you run agents with Strands Agents Tools, upgrade, rotate any credentials those agents could see, and review which secrets they can reach. The wider takeaway is that a safeguard the model can toggle isn’t a safeguard against untrusted input. Security-relevant settings belong in code the operator controls.